Determine your hardware requirements before your TIE server deployment by gathering reference metrics such as resource usage and capacity, latency impact and scalability, and caching benefits. Trellix performed these tests on different server-class systems.
The following information helps you determine the number of instances, location and level of server hardware, system core, memory, storage, and network bandwidth that TIE recommends for the components of your TIE software deployment. This information can help you make hardware purchasing and provisioning decisions.
This document assumes base knowledge of Trellix DXL infrastructure internals as described in the Trellix DXL Architecture Guide. Service Zones and Affinity should be used to optimize reputation requests.
Important
Results have been estimated or simulated using internal Trellix analysis or modeling and provided to you for informational purposes. Any differences in your system hardware, software, or network configuration might affect your actual performance. These are guidelines only; proof of concepts and incremental deployments are always recommended to understand the practical impact.
Estimating the number and location of TIE servers
The recommended deployment procedure involves running the solution in a small subset of the total managed endpoints to extrapolate the number of requests per second that will be required to handle.
Considering all the reference metrics in the following sections, use these guidelines when determining the number of TIE servers to deploy:
Always deploy at least two TIE servers instances, one primary and one secondary for fault tolerance. This supports up to 1000 requests per second in a dedicated infrastructure.
Place additional collocated TIE secondary servers to increase capacity as required, making sure multiplied replication bandwidth requirements are met by the network infrastructure. Consider latency impact on throughput when adding remote TIE secondary servers.
Switch to Write-Only primary Server to maximize replication potential for deploying multiple Secondaries. Add a Report-Only secondary server to concentrate load from Trellix ePO - On-prem reporting.
Rely on Reputation Cache servers when remote bandwidth is not enough to replicate the full reputations database or to increase the reputation throughput of reused files and certificates.
Reputation traffic is reduced significantly when endpoints have already cached reputations; however, spikes might be seen after endpoint upgrades (including content) as they clear their local cache.
Each customer vertical imposes different traffic characterization impacting the load against the TIE server capacity (file and certificate reuse and the number of new files are the key factors). For instance, companies in the financial vertical are expected to have more reuse and less unique files than those in the software research and development segment. To estimate requests coming from integrated gateways at the perimeter, product-specific dashboards can be used to dimension the number of requests.
As a basic rule 1000 requests per second can cope with traffic from 25000–50000 endpoints; and 500 requests per second can cope with traffic from 25000–50000 gateway users, assuming down-selection is properly configured to ask for the reputation of relevant files.
Make sure network requirements between the primary and every secondary are met by the networking infrastructure, available bandwidth should properly cover database replication needs.
Major deployments must avoid workload consolidation of virtual appliances on shared physical hosts and even consider running directly in bare-metal to avoid resource conflicts.
What is measured and determined
To determine the recommended sizing and performance guidelines, measure:
Resource usage and capacity
Latency impact and scalability
Caching benefits
Products tested
The following Trellix products at their recommended configuration were tested.
Trellix Agent 5.7.9.139
Trellix ePolicy Orchestrator - On-premises 5.10.0 (Build 2428) Update 14 and above
Trellix Data Exchange Layer 6.0.3.990.5
Threat Intelligence Exchange 2.3.0
Endpoint Security 10.7 September 2023 Update
The products were running over the following infrastructure.
VMware ESXi 6.0.0
ProLiant BL 460c G8
Note
The sizing and performance details mentioned are simulated only considering TIE 2.1.0, other Trellix product versions, and infrastructure versions listed above. The details will be updated with latest versions in near future.
Resource usage and capacity
This section describes resource usage when running the TIE solution over a few hours.
The objective is to show CPU, RAM, Disk, and Network usage metrics at peak load of the minimum recommended setup.
Test description
Run simulated worst-case scenario on mixed workload as seen on production environments against collocated primary/secondary setup for several hours. The Trellix DXL brokers are in a hub and service zones are enabled.
The workload requests were 30% of file reputation, 30% of certificate reputation, 15% of file metadata, 15% of certificate metadata, 2% of reputation synchronization and the remaining were reporting queries.
The environment has an average delay of 150ms on its Trellix GTI queries for new files. Endpoints are also simulated to be collocated with respect to TIE secondary servers having low latency access to them. The average latency between endpoints is 1ms with no dropped or corrupted packets.
The test sent sustained 1000 requests per second for 2 hours, with an overall of more than 7.3 million requests in 7,200 seconds, with an average response time of 76 ms and an error rate under 0.1%. 90% of file related requests ask for reputation and metadata of known files. 95% of certificate-related requests ask for the reputation and metadata of known certificates.
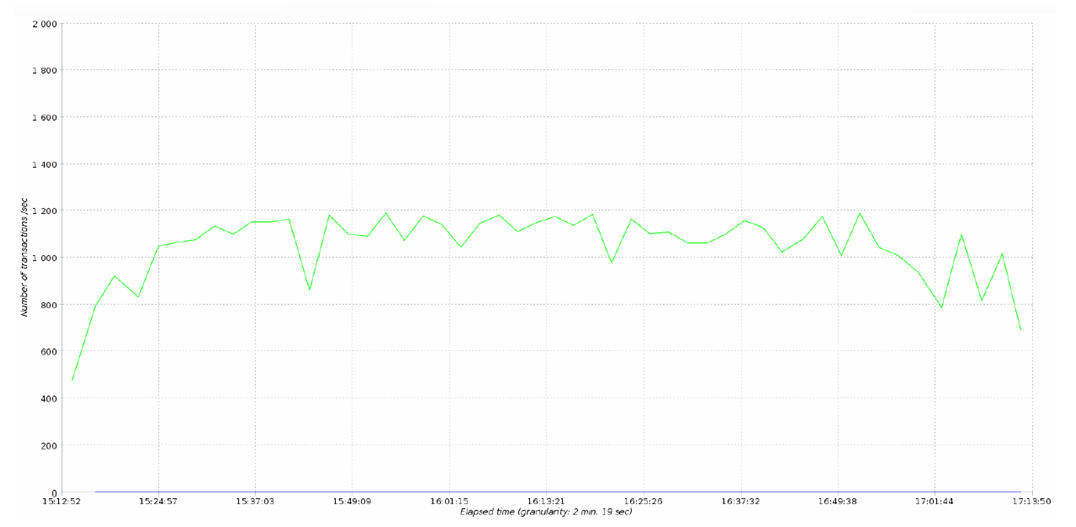
Use the following charts of resource usage for reference on CPU, RAM, Disk, and Network.
CPU
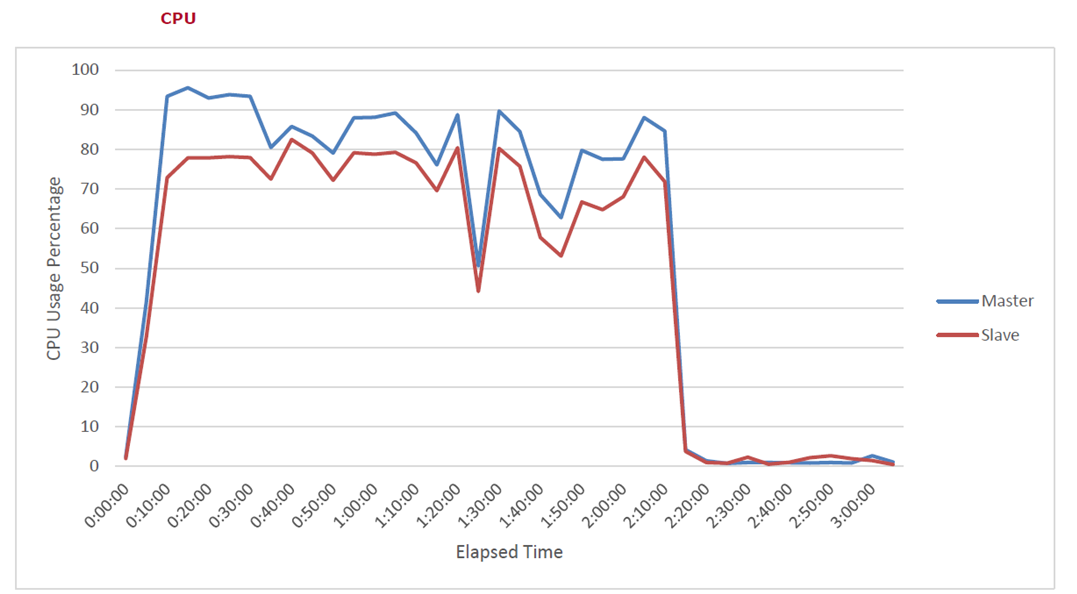
Average CPU usage is sustained at 80% when load stabilizes; after concluding the test, usage is back to idle. We monitored the CPU usage as a percentage of the interval metric provided by VMWare vCenter.
RAM
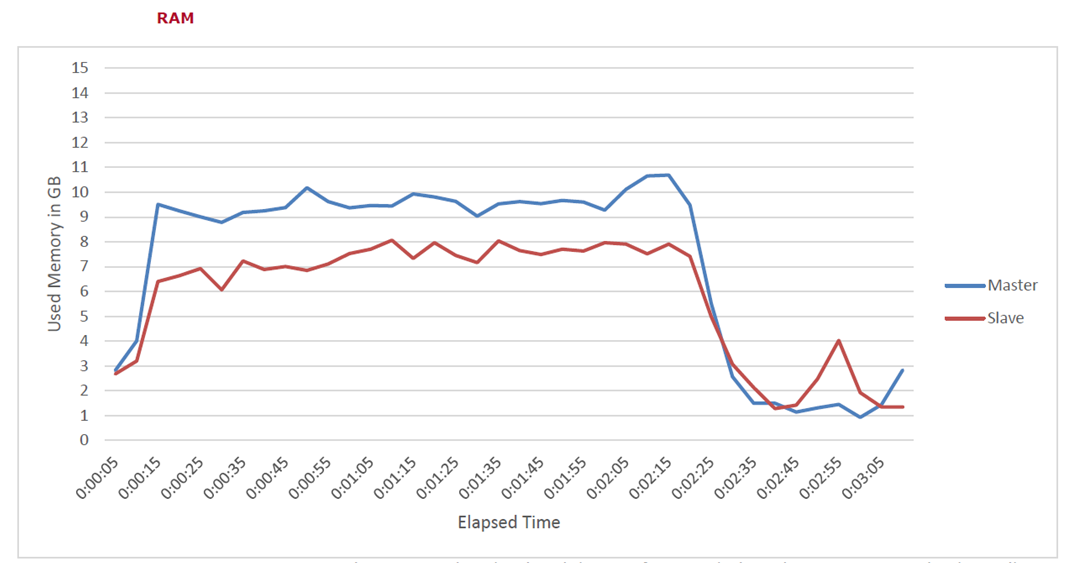
Memory usage is sustained at 10 GB when load stabilizes; after concluding the test usage is back to idle. We monitored the amount of memory that is actively used metric provided by VMWare vCenter.
Disk
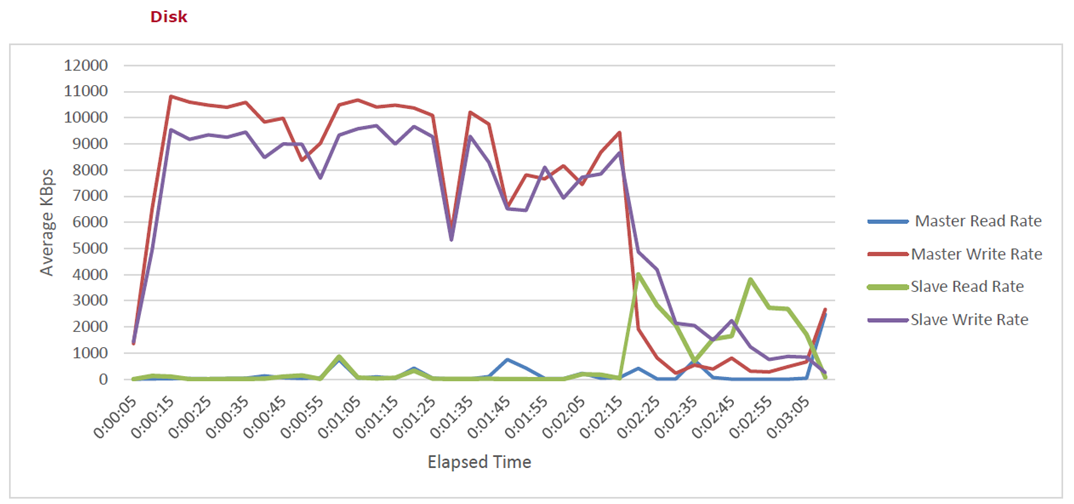
Average disk read and write usage is sustained at 10,000 KBps when load stabilizes; after concluding the test disk usage is back to idle. We monitored the Average number of kilobytes written and read to disk each second provided by VMWare vCenter
Network
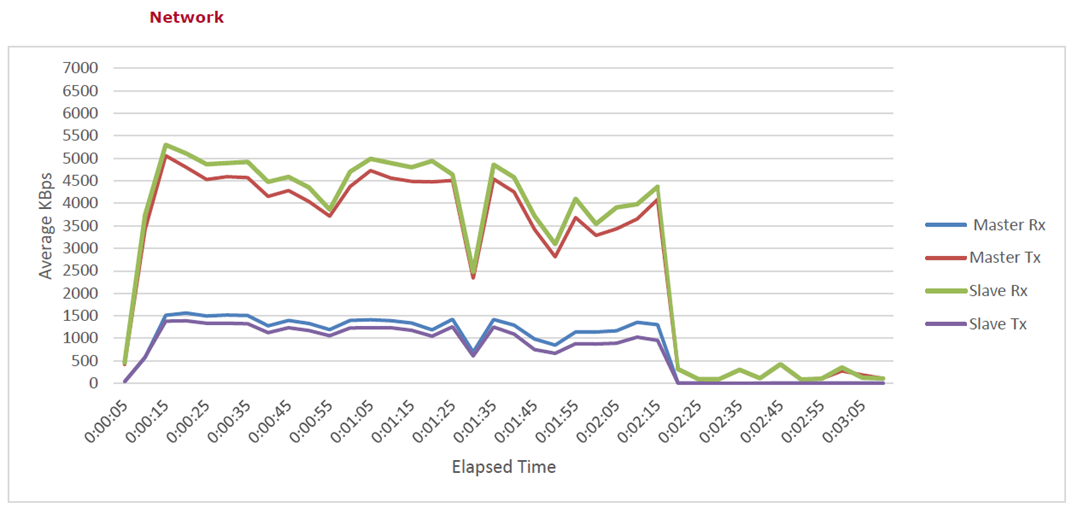
Primary data received is sustained at 1000 KBps and transmitted at 4500 KBps when load stabilizes. Secondary data received is sustained at 4500 KBps and transmitted at 1000 KBps when load stabilizes. We monitored the average rate at which data was received or transmitted during the interval provided by VMWare vCenter.
Note that database streaming replication is optimized for minimal replication delay so it uses as much bandwidth as available. Each new replicating secondary will increase bandwidth requirements approximately linearly as shown above as replication happens point-to-point between primary and every secondary using direct links.
This test includes combined Trellix DXL requests and database replication in LAN, plus access to Trellix GTI in WAN. Real replication bandwidth depends on latency and dropped packet ratio. If replication happens through a noisy link, synchronization might not find enough usable bandwidth to be updated.
Latency impact and scalability
This section describes the latency impact on throughput when adding new secondary servers to the minimum recommended setup. The objective is to measure the throughput capacity difference as latency is added.
Test description
Run simulated worst-case scenario on mixed workload as seen on production environments against a primary plus a remote secondary setup for several hours.
The test sent sustained requests per second against a remote secondary placed under different latency delays. The resulting throughput on each case shows the impact caused by latency.
While processing requests, secondary issues update to the primary database that queues up internally until served. Non-trivial latency between primary and secondary might cause the internal queue to fill up which ends up in service disruption in case of sudden spikes of load.
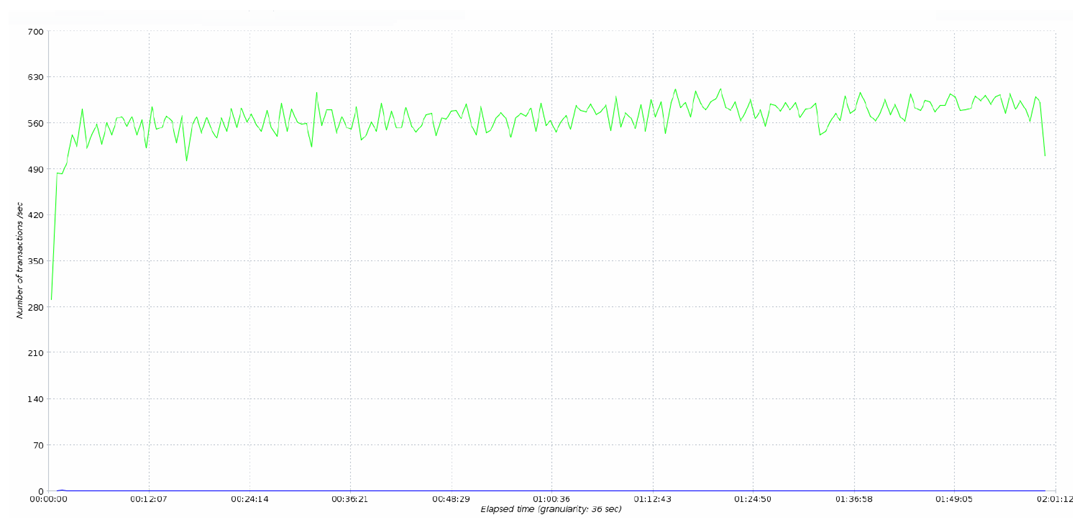
Scenario 1: No latency
A collocated secondary handle sustained a workload of up to 500 requests per second.
Scenario 2: Remote site
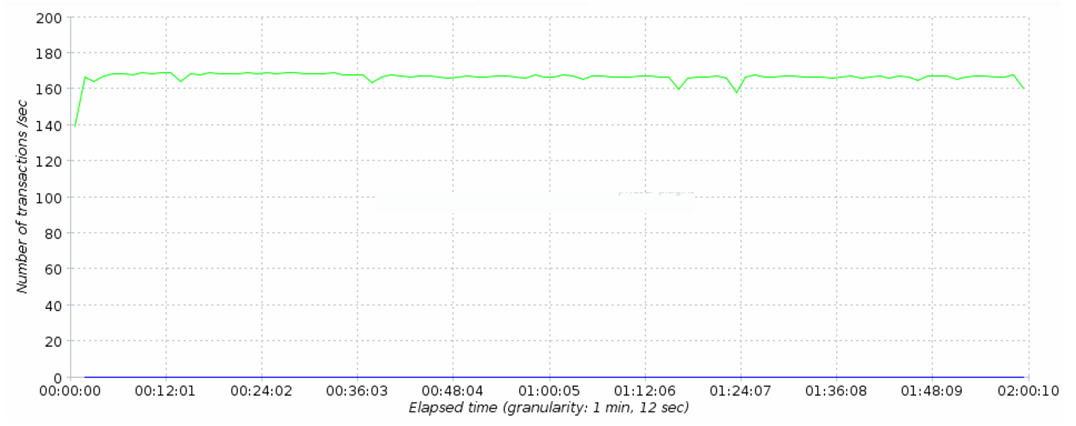
A secondary placed off-site, but still in the same region has a latency of 100 ms ± 10 ms, can handle the sustained workload of about 170 requests per second.
Scenario 3: Remote region
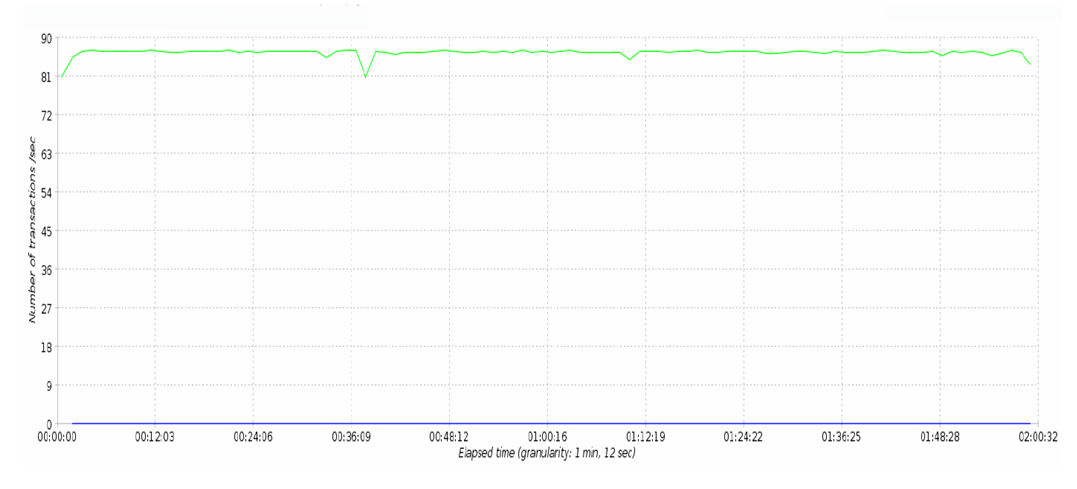
A secondary placed in a remote region having latency of around 200 ms ± 20 ms can handle the sustained workload of about 85 requests per second.
Caching benefits
This section describes caching impact on required bandwidth and throughput when adding TIE Reputation Cache servers. The objective is to measure reduced network requirements and increased service throughput when implementing cached reputation stores.
Test description
Run simulated worst-case scenario on mixed workload as seen on production environments against a primary and secondary setup plus a remote TIE reputation cache to understand the impact. First, measure the network consumption of forwarding and caching reputation requests instead of replicating the full reputation database. Second, dimension how throughput is increased when pairing a reputation cache with a secondary.
Scenario 1: Remote reputation cache
The same workload used to dimension resource usage and capacity above was executed against a remote reputation cache having a latency of 100 ms ± 10 ms against a collocated pair of primary and secondary.
A TIE reputation cache server shows sustained network consumption of close to 1200 KBps in comparison with the close to 4000 KBps required in the first test scenario to cope with full database replication
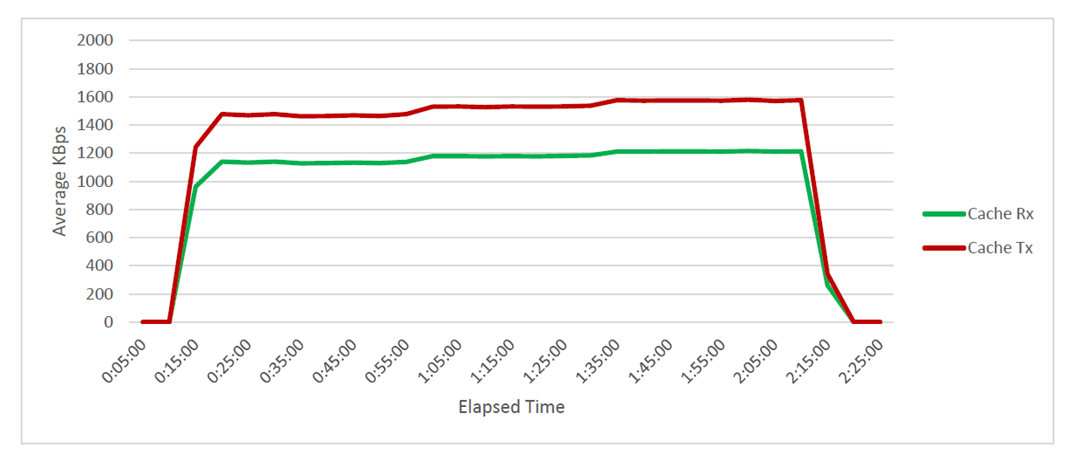
The cache increases effectiveness when file reuse is significant and there are few unique files.
While processing requests, the TIE reputation cache server forwards requests of new files and certificates, and it will cache them for future use.
The in-memory cache is kept updated based on a combination of reputation change broadcasts and an internal time-to-live of each stored item. File prevalence is periodically updated to the primary or secondary's as required.
Scenario 2: Local reputation cache
The same workload used to dimension resource usage and capacity above was executed against a remote secondary and reputation cache having a latency of 100 ms ± 10 ms against a primary instance.
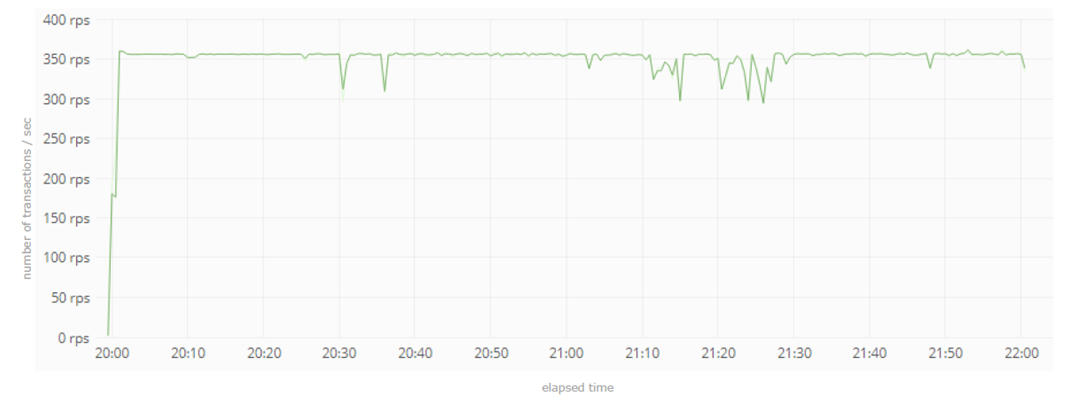
The TIE reputation cache server only helps to increase the throughput of reused file and certificate reputation requests. Primary and secondary servers should be deployed to cover spikes on new files.
Multiple TIE reputation cache instances can be placed inside different Trellix DXL Service Zones with a single secondary without significant impact in bandwidth for the reputation of reused files and certificates.